Self-improving policies expose new failure patterns, which changes what their judges must verify, and fixed judges limit the feedback they get.
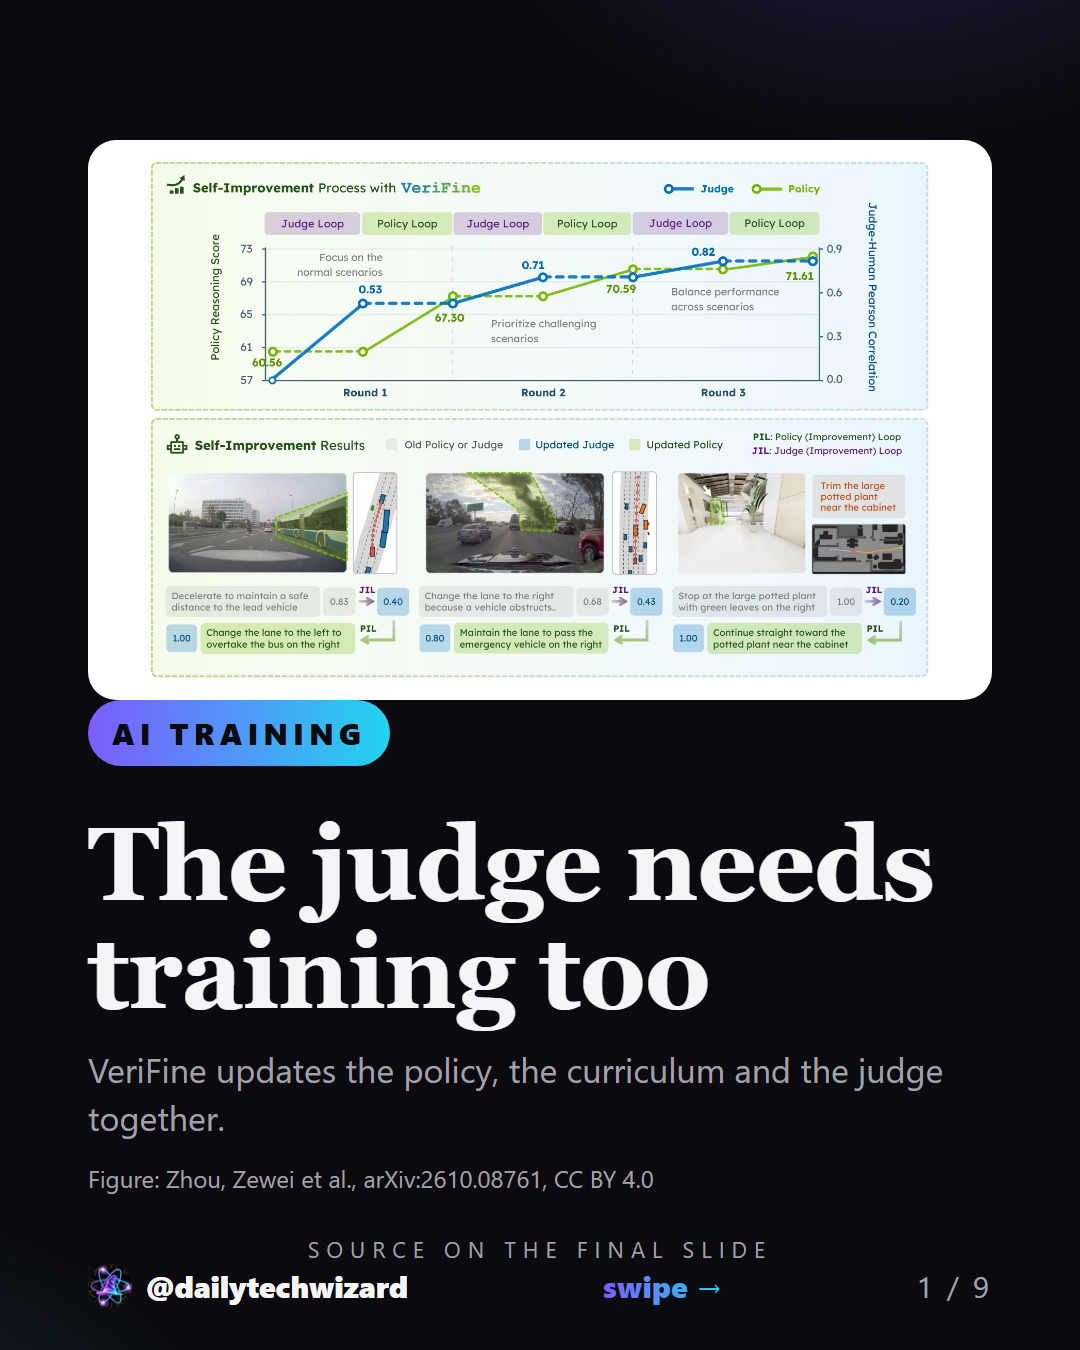
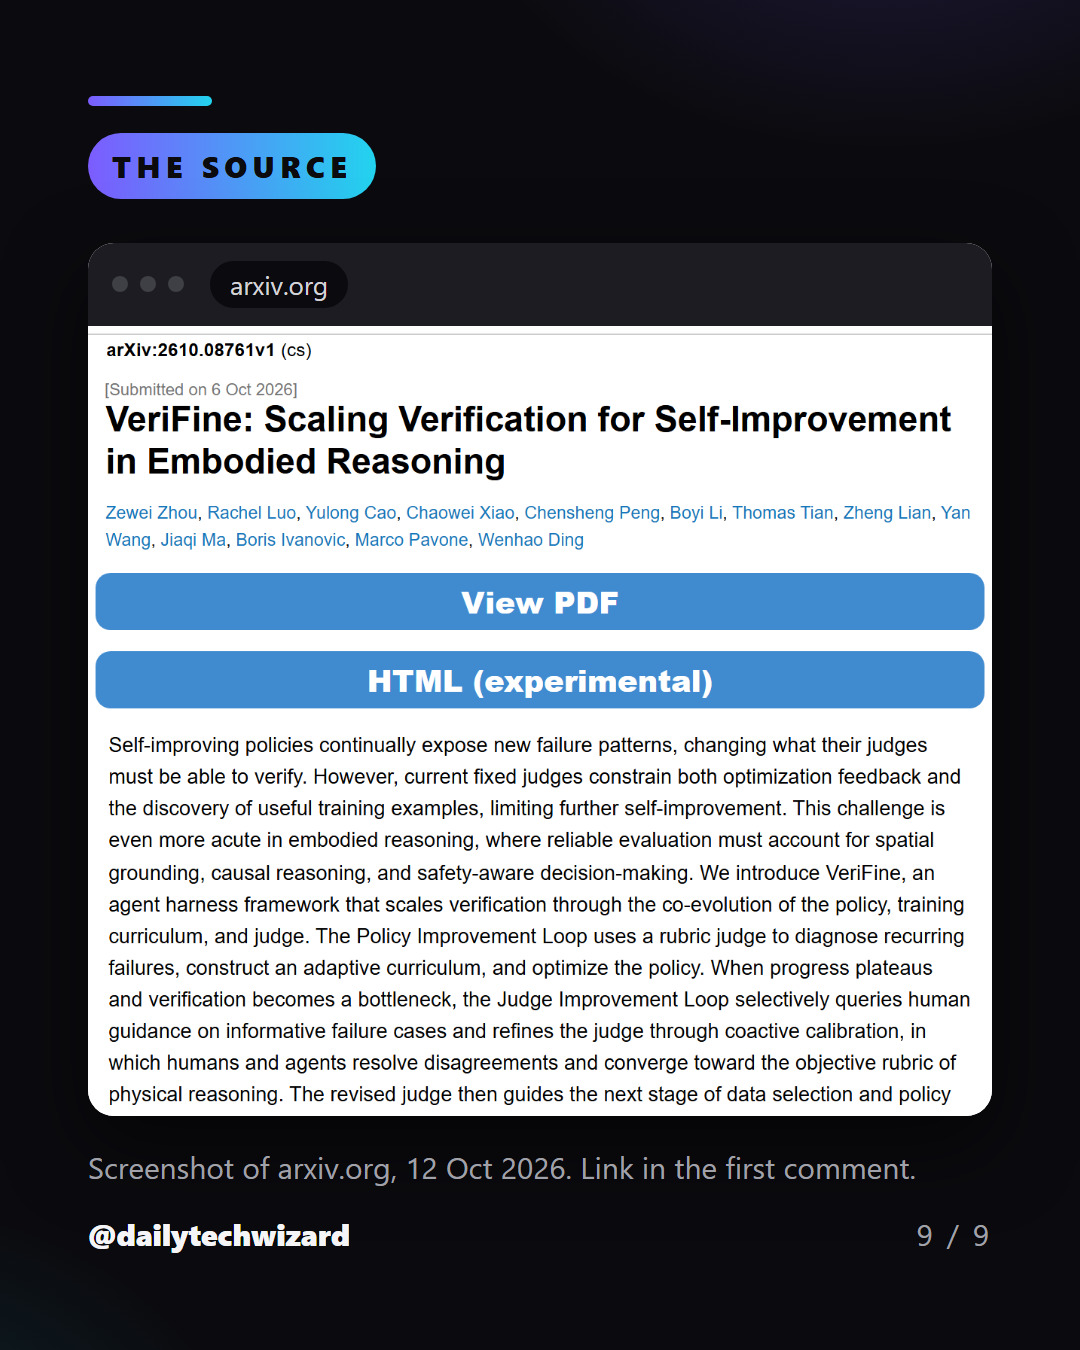
Self-improving policies expose new failure patterns, which changes what their judges must verify, and fixed judges limit the feedback they get. VeriFine, from Zewei Zhou and colleagues, updates the judge alongside the policy and the training curriculum. When progress stalls, it asks humans for guidance on informative failure cases. The experiments cover driving and robot navigation. Source: link in the first comment Cover figure: Zhou, Zewei et al., arXiv:2610.08761, CC BY 4.0 (http://creativecommons.org/licenses/by/4.0/), https://arxiv.org/abs/2610.08761