Z.ai's GLM-Legal passes 19.17% of Harvey legal AI tasks
Z.ai's new legal AI model passes 19.17% of tasks on Harvey's Legal Agent Benchmark, nearly triple the 6.67% its base model manages.
A legal AI model nearly triples its base score. A new legal AI model costs cents per test on Harvey's benchmark, but it still fails most of its tasks.
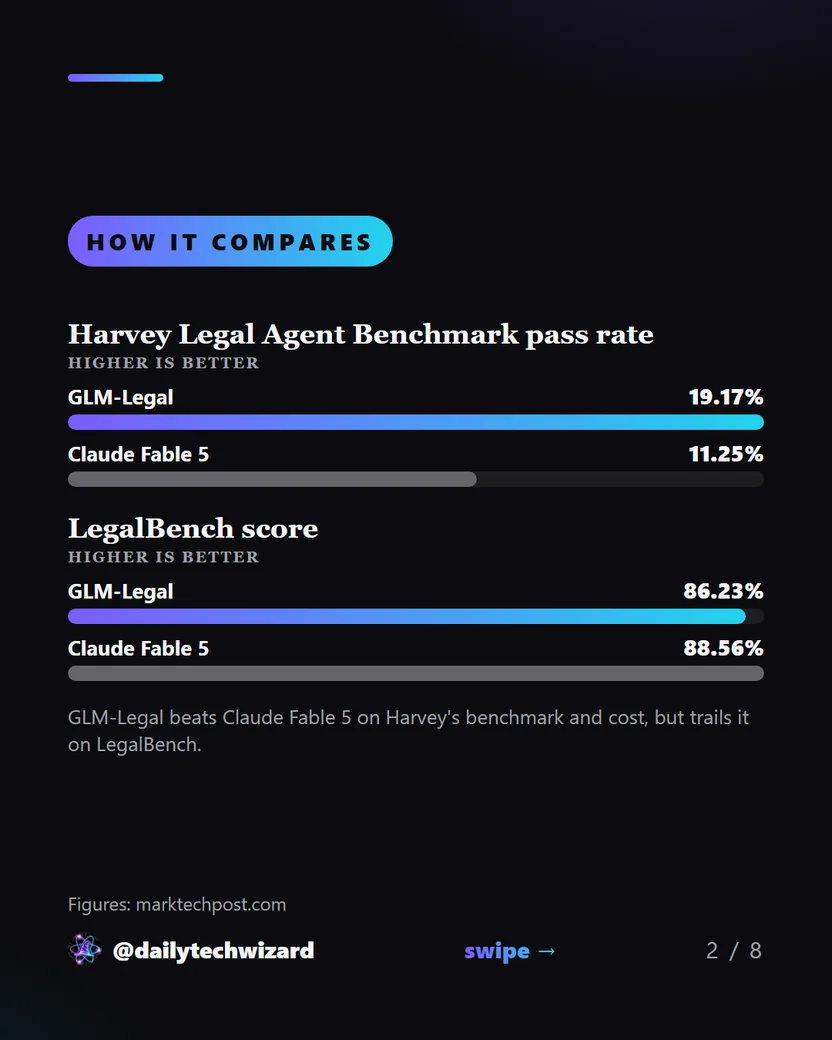
Harvey Legal Agent Benchmark pass rate: GLM-Legal 19.17%, Claude Fable 5 11.25%. LegalBench score: GLM-Legal 86.23%, Claude Fable 5 88.56%. GLM-Legal beats Claude Fable 5 on Harvey's benchmark and cost, but trails it on LegalBench.
Built for agentic legal work. Z.ai's GLM-Legal is built on GLM-5.3-Flash and trained for contract review, evidence analysis and compliance research.
19.17% against 6.67%. On Harvey's Legal Agent Benchmark, GLM-Legal passes 19.17% of tasks. Its base model passes 6.67%. A task passes only if every criterion passes.
Ranked #7 of 79 on Vals AI. It ranks ahead of Kimi K3 (12.92%), Claude Fable 5 (11.25%) and GPT-6 Astra (5.42%). Six higher-ranked models are missing from Z.ai's chart.
$0.15 a test, 1h12m a run. Vals AI puts GLM-Legal at $0.15 per Harvey LAB test, against $19.23 for Claude Fable 5. An average run takes 1h12m.
Mixed results on other tests. On LegalBench it scores 86.23%, behind Claude Fable 5's 88.56%. On Legal Research Bench it gets 41.83%, below its base model's 45.19%.
Training ran in two stages: mid-training on expanded legal corpora, then reinforcement learning across tens of thousands of legal task environments.
The API is application-only with no published price, and no GLM-Legal repository existed on Hugging Face as of October 13, 2026. The base model is available now at $0.15 / $0.50 per 1M tokens.
Does a cheap legal AI that fails most tasks still seem useful to you?