NVIDIA releases open agentic model Nemotron 3.5 Super VL
NVIDIA has released an open model that it says has accuracy comparable with its largest reasoning model on agentic tasks at roughly one-fifth the size.
NVIDIA's smaller model, aimed at big jobs. NVIDIA says a model one-fifth the size of its largest reasoning model has comparable accuracy, and organizations can customize it.
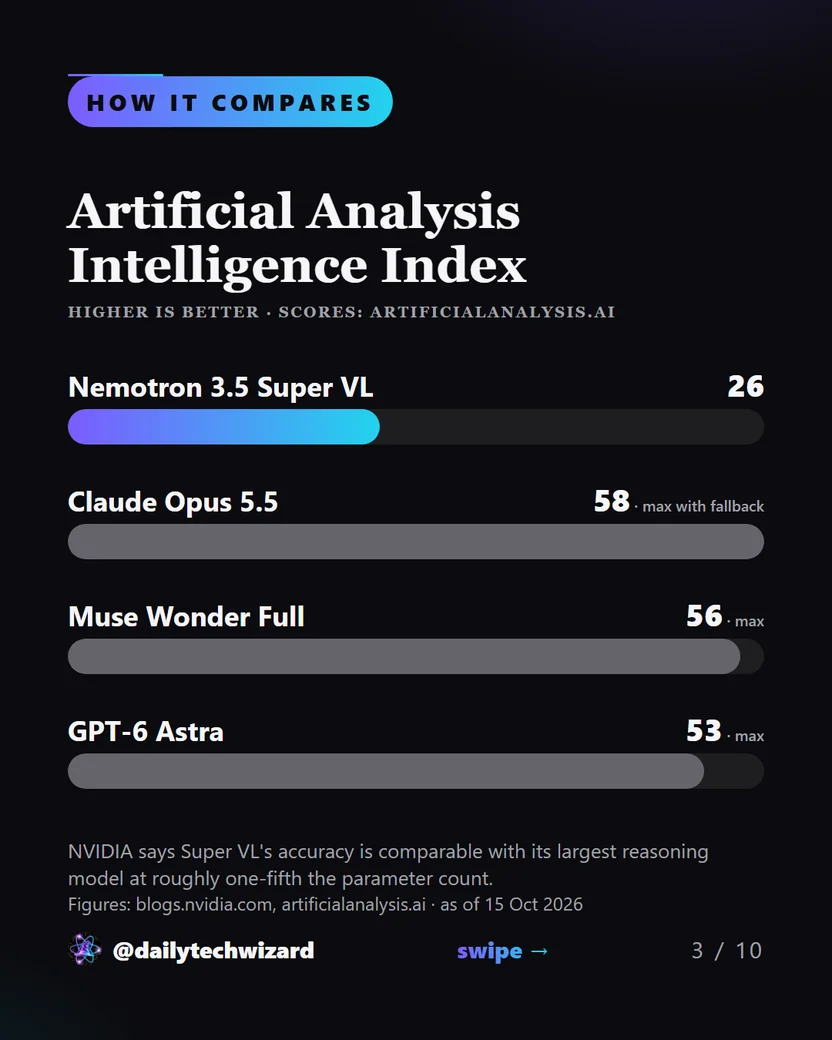
Artificial Analysis Intelligence Index: Nemotron 3.5 Super VL 26, Claude Opus 5.5 58 (max with fallback), Muse Wonder Full 56 (max), GPT-6 Astra 53 (max). NVIDIA says Super VL's accuracy is comparable with its largest reasoning model at roughly one-fifth the parameter count.
Comparable accuracy at one-fifth the size. NVIDIA says Nemotron 3.5 Super VL, at 120 billion parameters, has accuracy on agentic tasks comparable with its largest reasoning model at roughly one-fifth the parameter count.
It reads images, webpages and PDFs. It handles text recognition, tables and charts, so agents don't have to route work between separate systems.
Open weights, data and training recipes. Organizations can post-train it on their own data and run it on their own infrastructure.
Who is already customizing it. Scale AI post-trained it for Skydance and EY agents. Atlassian is integrating it for Jira and Confluence search, and Perplexity for search.
Two edge models join it. Bolt 74B-A9B fits in 24GB of memory and is available now. Bolt E4B 4GB, for local voice assistants, arrives Oct. 23.
The model is Nemotron 3.5 Super VL, with 120 billion parameters. NVIDIA says its accuracy is comparable on instruction following, tool use, multistep business workflows and visual understanding. It also calls Super VL the fastest open agentic model in its class, citing the Artificial Analysis Intelligence Index leaderboard for up to 5x faster throughput than other models in its class.
NVIDIA says dozens of organizations are customizing it. Scale AI post-trained it for Skydance's vendor credit finance agent and EY's M&A due diligence agent. AfterQuery tuned it for Hebbia, and Mercor trained it for coding agents. Atlassian is integrating it for agentic search across Jira and Confluence, and Perplexity for search and agentic tasks.
Two edge models join it. Bolt 74B-A9B uses native 2-bit quantization to fit in 24GB of memory. Bolt E4B 4GB targets local voice assistants and embedded interfaces. Super VL and Bolt 74B-A9B are available now, and Bolt E4B arrives Oct. 23.
Would you run an open model like this on your own hardware?
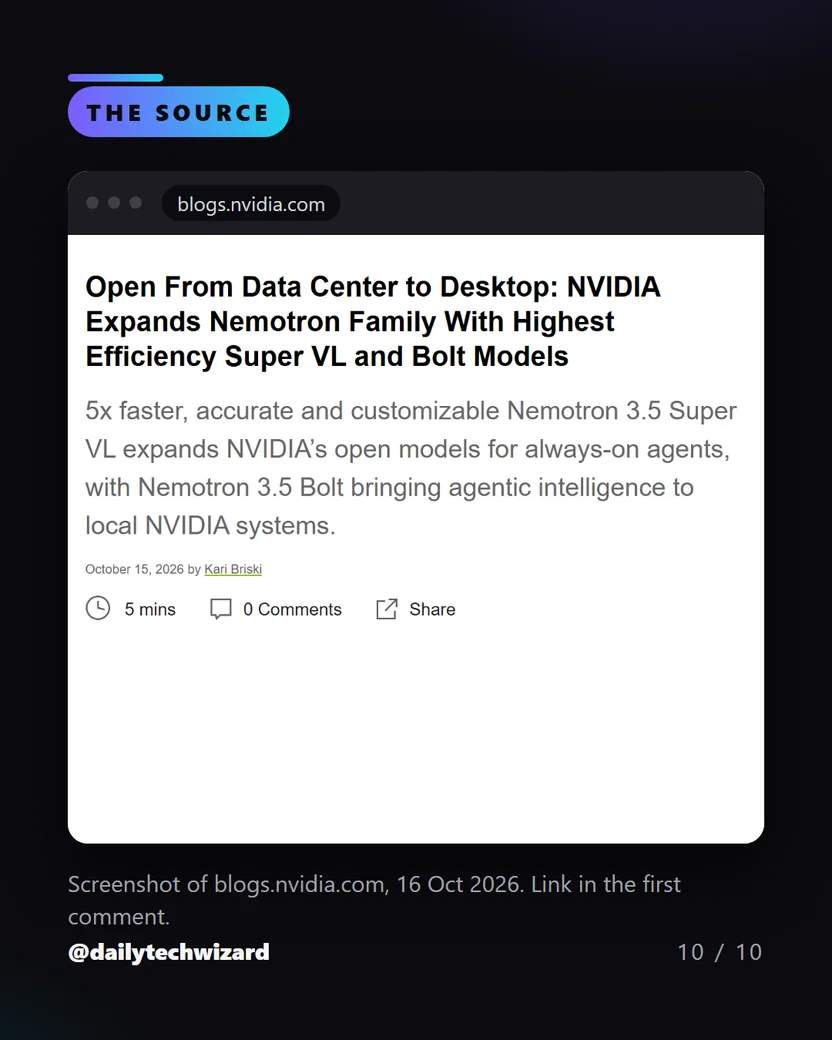
Cover image: blogs.nvidia.com